Your AI history is a data asset.
PHIORA DATA lets you voluntarily archive your LLM usage history, protect sensitive information, and earn points for verified AI data contributions.
- Consent-based
- Cleaned of personal data
- Raw data is never sold
Points are not tokens and do not guarantee any financial value. Review is still manual.
Removed before review
The real cleaner (@phioradata/shared) is running right now, in this tab. Not a recording.
- Scanning…
Dashboard stats on the left are illustrative, not real account data. The Cleaning panel on the right runs the same production code, live in this tab.
Built on
- Robinhood Chain 46630
- Ed25519 Constitutional Data v1
- Supabase RLS + private bucket
- Soulbound receipt provenance
Upload. Clean. Earn.
How PHIORA DATA works
Three steps, from a file on your computer to points in your account, with provenance proof anyone can verify.
Upload your AI history
One .txt file, max 2MB. Export your conversations from ChatGPT, Claude, Grok, or Gemini. Signed on your device before it is sent.
We clean sensitive data
Email addresses, phone numbers, URLs, API keys, wallet addresses, credit card numbers, ID numbers, private keys, and seed phrases are removed from the copy that gets reviewed.
Earn contribution points
The reviewer reads the cleaned copy, not your original file. Once approved: points = 100 + quality score ×2 + size in KB ×0.1, and your tier rises as you contribute.
Why it matters
Your AI history has value.
Real human-AI interaction data is the foundation for the next wave of models, agents, and workflow intelligence.
Real human-AI interaction
Authentic prompt-and-response patterns are increasingly valuable for training the next generation of models, agents, and workflow intelligence.
Workflow intelligence
How people chain tools together and refine prompts reveals real productivity behavior, data that synthetic datasets cannot replicate.
Task-aware categorization
Coding, marketing, research, and productivity each shape model behavior differently. Categorized data leads to better fine-tuning.
Privacy first
Built on consent. Designed for privacy.
Privacy is not a feature here. It is the foundation of the contribution model. What follows is not a promise, but how the system is actually built.
Raw data is never sold.
Your original file stays in a private bucket that can only be opened with a five-minute signed URL. Reviewers have no read policy on that bucket at all.
Sensitive information is removed.
Nine categories are detected and replaced with markers before the copy is stored. You see the redaction count and a preview of the result as soon as the upload finishes.
You stay in control.
View, download, or delete any dataset at any time. Permissions are granted per purpose, and can be revoked with a single switch.
Points are not tokens.
Points do not guarantee any financial value. Any token-related benefits, if they come, will only follow policy and regulatory review.
Nine categories removed
Specific categories are processed first so that general patterns like URLs don't swallow part of a sensitive value and leave a fragment behind.
- seed phrase
- private key
- wallet address
- API key
- credit card
- ID number
- phone number
- URL
Cleaning is pattern-based, so it isn't perfect. A local number written as 0812-3456-7890, for example, isn't caught by the current phone pattern. That's why you see a preview of the result, and can delete your archive at any time. Try the cleaner in your browser.
The left-hand lines are illustrative; the right-hand column is not. All four lines are run through the same cleaner used in production.
Who can read what
5-minute signed URL| Data | You | Reviewer | Public |
|---|---|---|---|
| Original file (raw) | Yes | No | No |
| Cleaned copy | Yes | Yes | No |
| Email address | Yes | No | No |
| Filename & redaction count | Yes | Yes | No |
| Public handle | Yes | Yes | Only if you enable it |
| Approved dataset receipt | Yes | Yes | Yes |
Data types
What kind of AI data PHIORA DATA structures
Prompt patterns
Structural patterns in how users phrase requests across tasks, domains, and tools.
AI workflow data
Multi-turn flows: how people refine outputs, switch context, and orchestrate tools.
Human-AI interaction
Real-world, long-running conversational behavior across major LLM platforms.
Constitutional Data v1
You can verify it yourself.
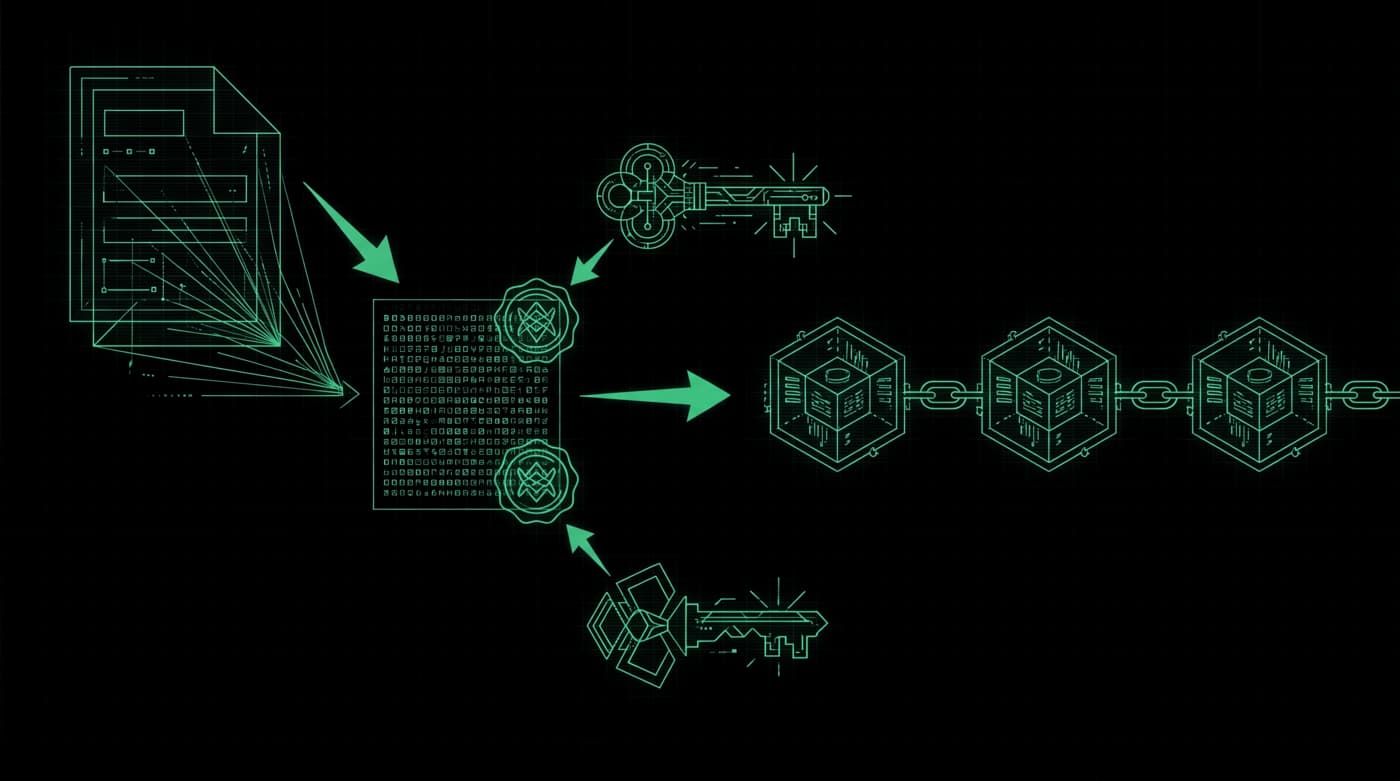
Every approved dataset comes with a receipt carrying two Ed25519 signatures: yours, created on your device before the file is sent; then ours, after cleaning and review pass.
phioradata.v1 | scope | sha256(data) | nonce | timestamp
The issuer's public key is published at https://srv1944250.hstgr.cloud/.well-known/phioradata-pubkey.json. A single dataset's receipt can be fetched at https://srv1944250.hstgr.cloud/api/provenance/<dataset_id>. Your private key never reaches the server. That's what separates a signature from a mere claim on a marketing page.
The receipt is also recorded as a soulbound token on Robinhood Chain if you register a wallet address. That recording is best-effort: without a wallet, the product runs fully off-chain.
Limits
What we can't promise yet.
This page sells transparency, so the limits are written here, not in a footnote.
- StatusBeta on Robinhood Chain (chain 46630). Not a production network; records are not a permanent guarantee.
- CleaningPattern-based, so it is not perfect. Personal data in an unusual format can slip through. That is why there is a preview.
- Original fileStays stored in a private bucket. What gets cleaned is the copy the reviewer reads.
- PointsNot a token and do not guarantee any financial value.
- ReviewStill manual. No turnaround-time guarantee, and not every upload gets approved.
- Usage limitsOnly upload conversations that are your own. Do not upload data that truly should not leave your device.
Join the AI usage data layer
Turn your AI usage history into a valued data asset.
Built on consent. Designed for privacy. Powered by contribution.